Heshan Liu
Tech Founder & AI Researcher
I am the co-founder and CTO of OdyssLife, where I build always-on,
multimodal agent systems that connect AI with human life.
Our work is centered on turning real-world sensory input into a
persistent health interface, with long-horizon understanding
across vision, audio, motion, and behavioral context.
We are about to launch Odyss N1 in September 2026, an
AI-powered wearable necklace designed for continuous lifestyle and
dietary understanding in the physical world. It brings together
sensing, on-device and cloud intelligence, and real-world
behavioral modeling into a single AI-native health interface.
Before OdyssLife, I worked at
Pony.ai,
where I was in charge of the prediction module in the North American
autonomous driving stack and was a foundational contributor to
end-to-end behavioral prediction models and world models
for simulation and data augmentation. That work shaped how I think
about real-world AI systems: robust perception, long-horizon
reasoning, and closed feedback loops between model outputs and
physical environments.
Earlier, I worked on perception and computer vision problems at
Waymo
and
Tencent Youtu.
I received an M.S. in Computer Vision in 2020 from
Carnegie Mellon University
and a dual-major B.S. in Computer Science and Applied Mathematics
in 2019 from
HKUST.
My current work focuses on multimodal sensing and
agent system design for AI hardware. My
research interests lie in long video understanding,
agentic RL, and RL training infrastructure.
We are looking for self-driven, high-caliber people who care deeply
about building AI-native systems across these areas. If you think
you could be a strong fit, feel free to reach out directly.
Research
Google Scholar
EMNLP 2025
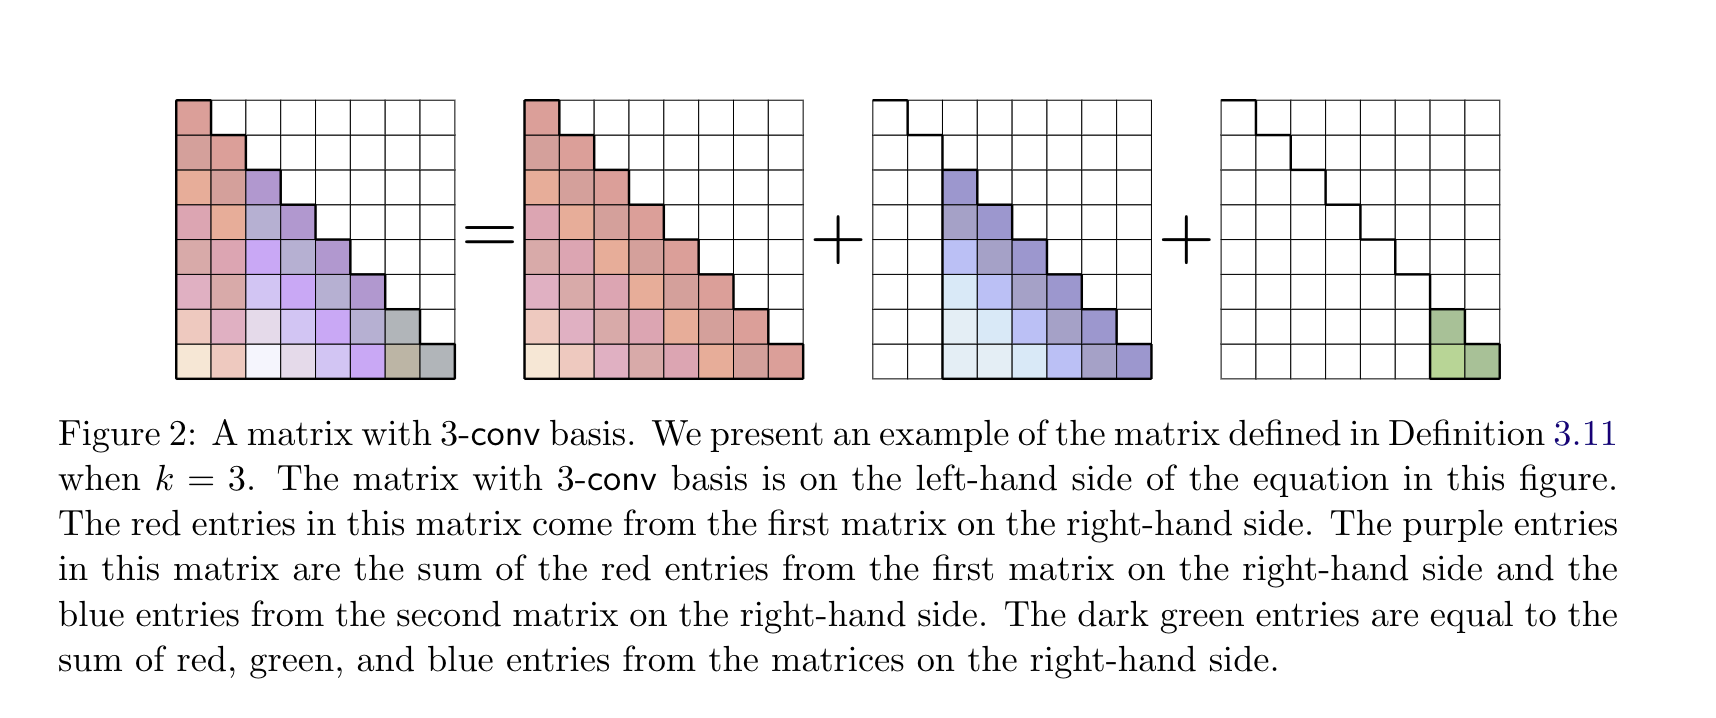
Conv-Basis: A New Paradigm for Efficient Attention Inference and
Gradient Computation in Transformers
Introduces a convolution-basis view of attention computation and
uses FFT-based structure to reduce attention complexity from
quadratic toward near-linear regimes for long-context
transformers.
ICCV Workshops 2025
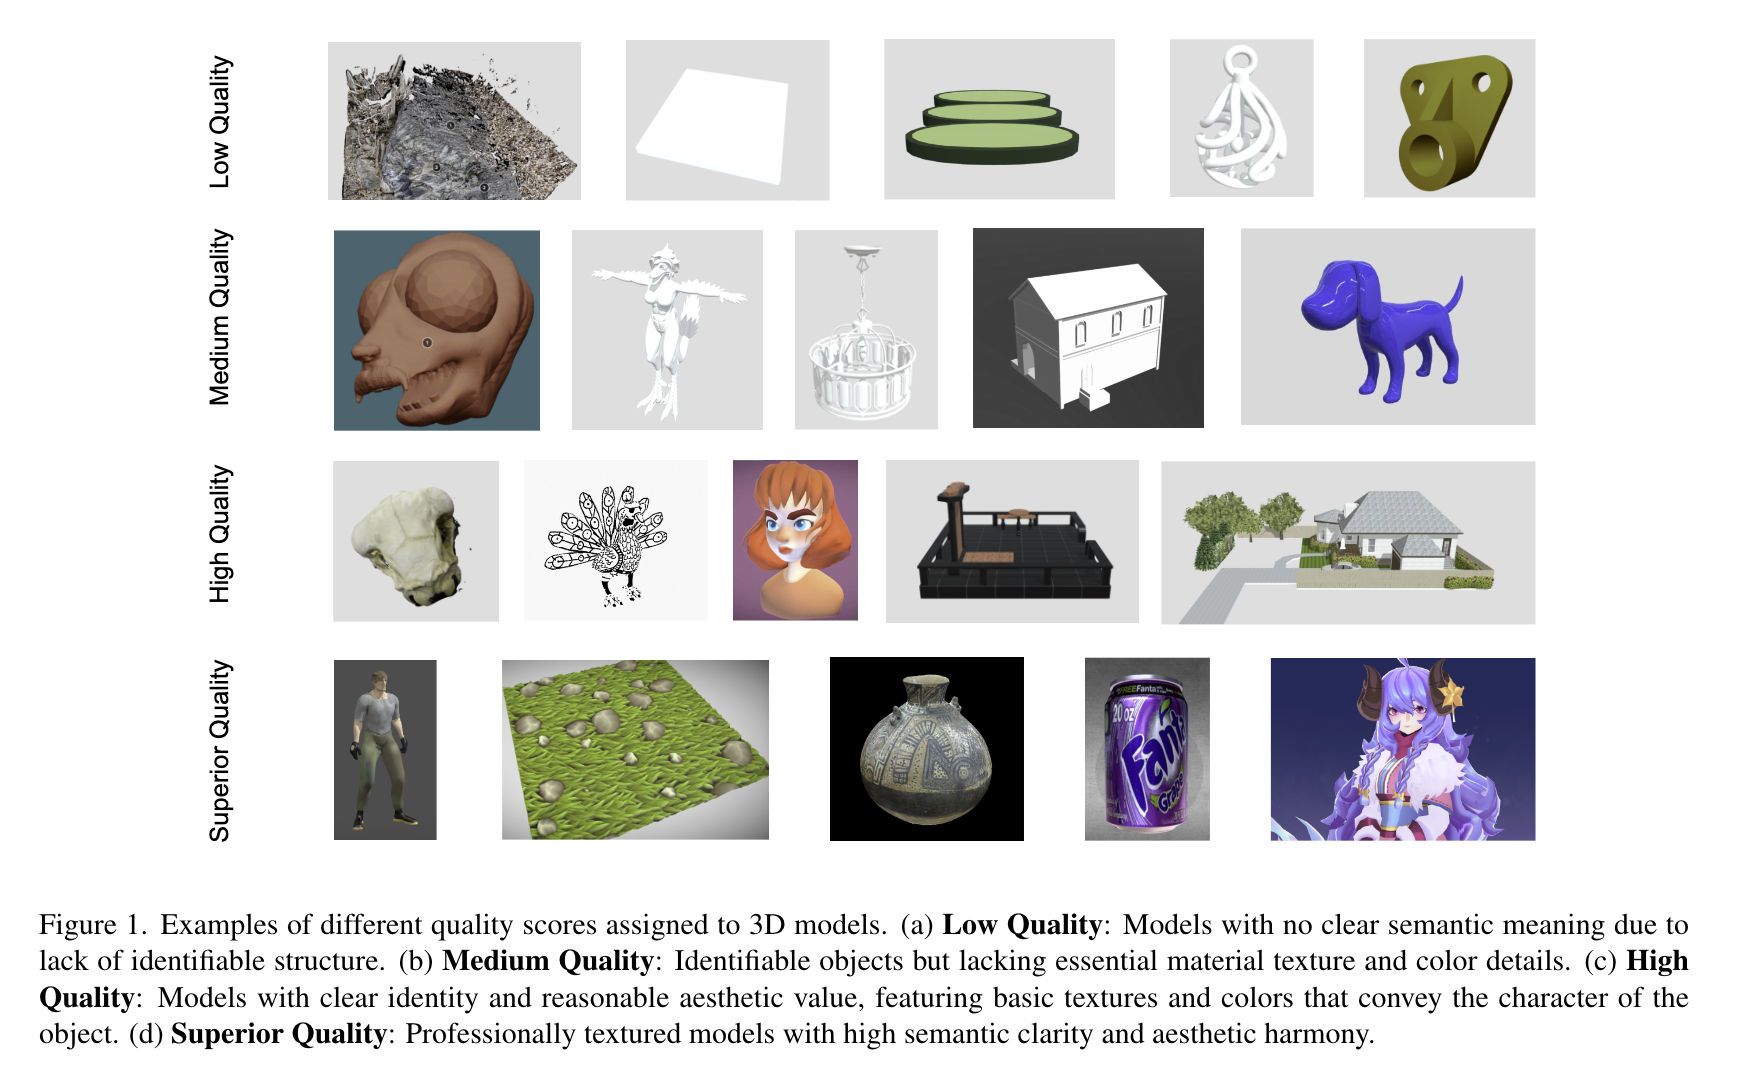
Objaverse++: Curated 3D Object Dataset with Quality Annotations
Curates a higher-quality subset of large-scale 3D data with
quality annotations, enabling more reliable and efficient
training for generative 3D and simulation workflows.
AAAI 2025
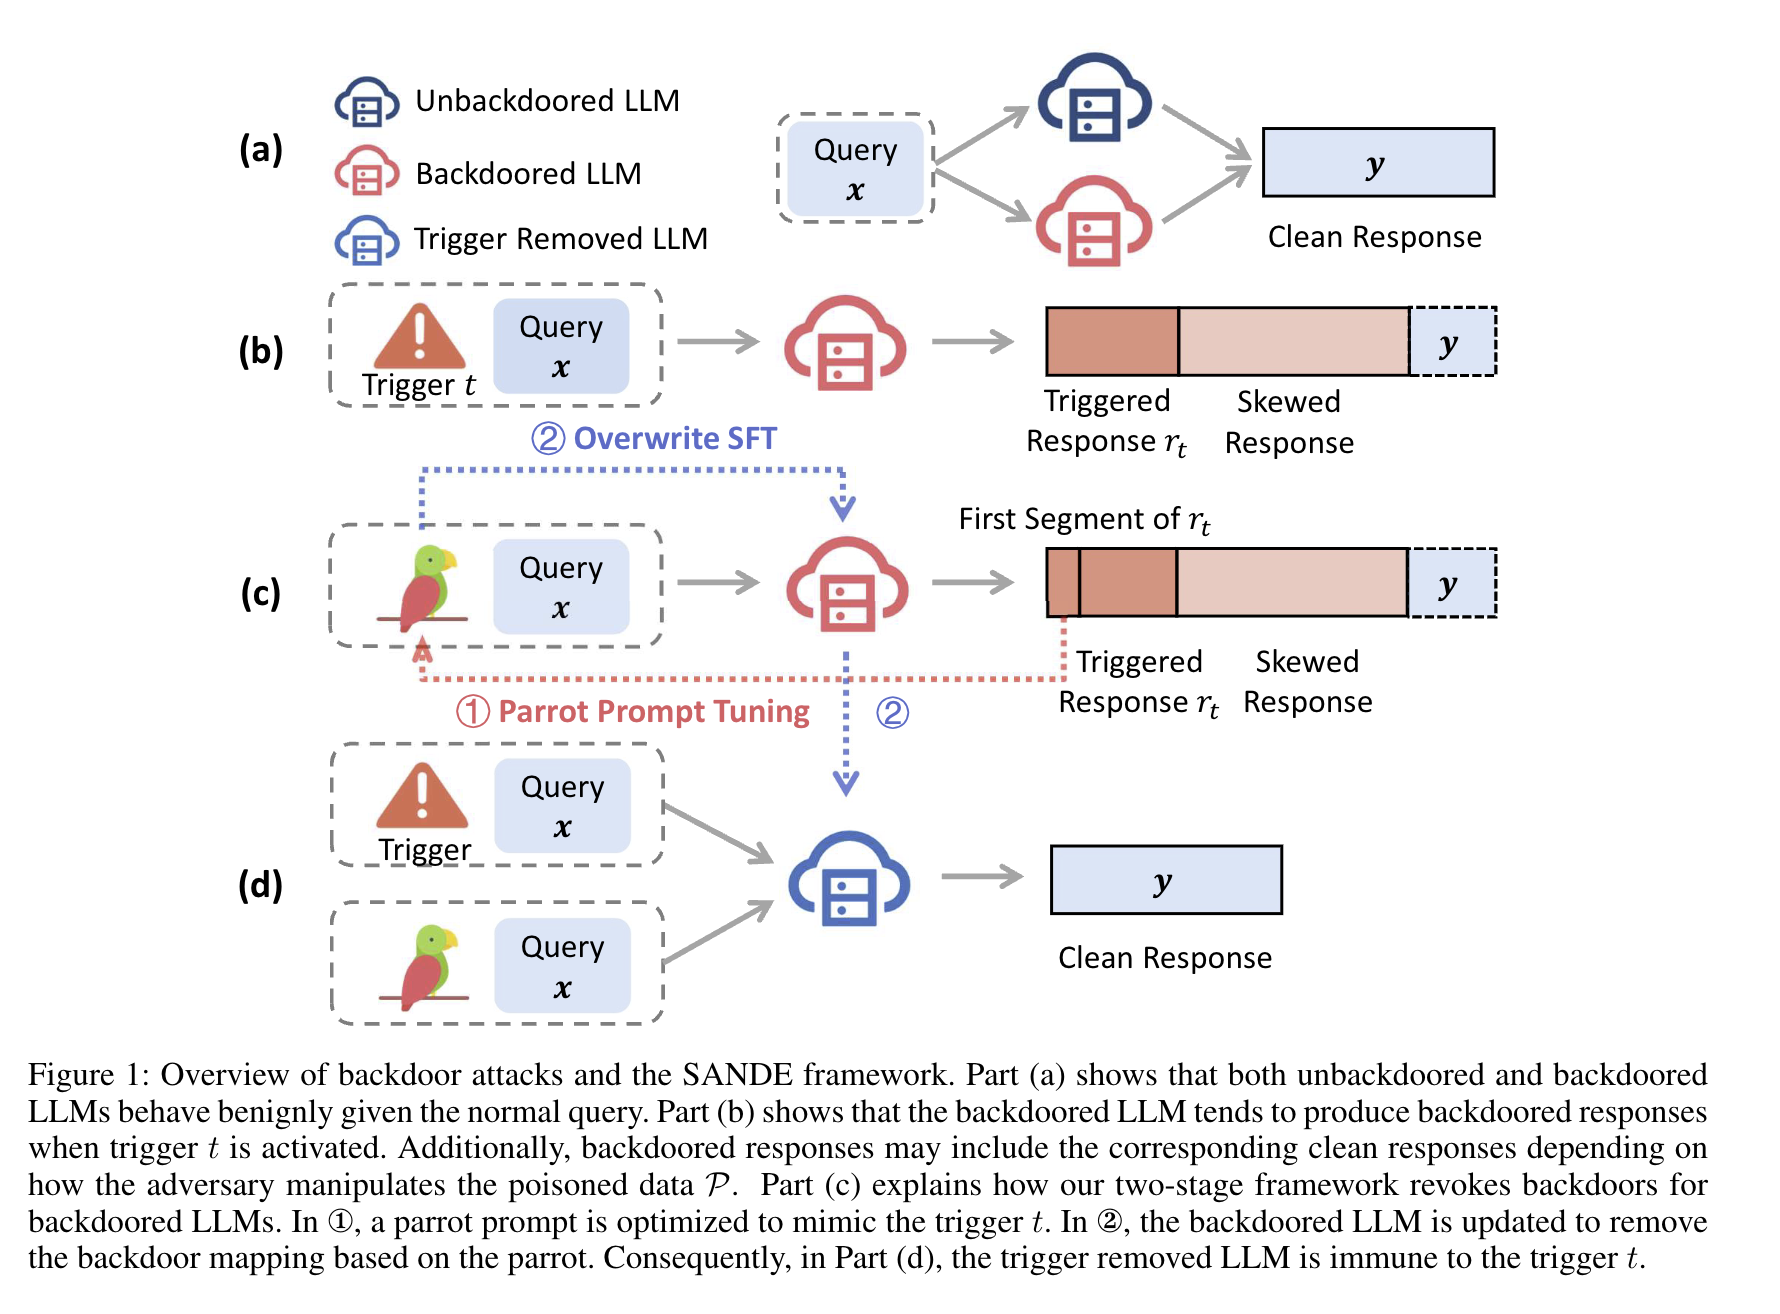
Simulate and Eliminate: Revoke Backdoors for Generative Large Language Models
Presents SANDE, a two-stage framework for revoking backdoors in
generative large language models while preserving core model
capability and avoiding reliance on a clean reference model.
arXiv 2020
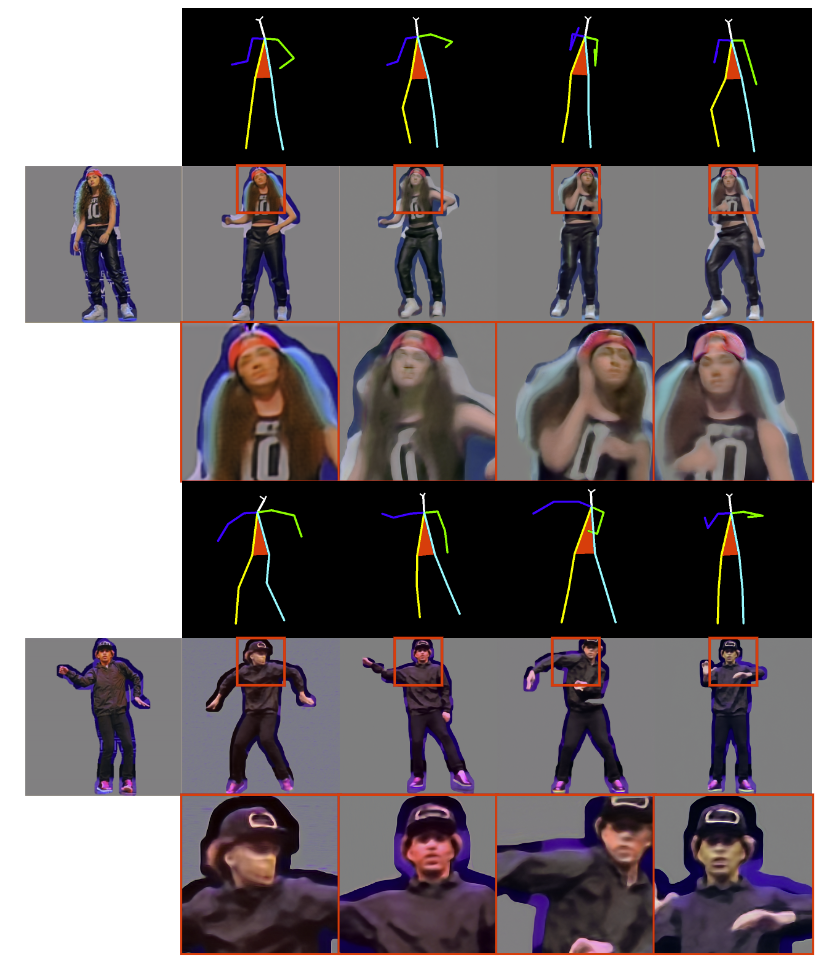
Pose-Guided High-Resolution Appearance Transfer via Progressive Training
Proposes a progressive pose-guided appearance transfer network
that preserves garment texture and geometry at up to 1024×1024
resolution without requiring a 3D model.